Description:
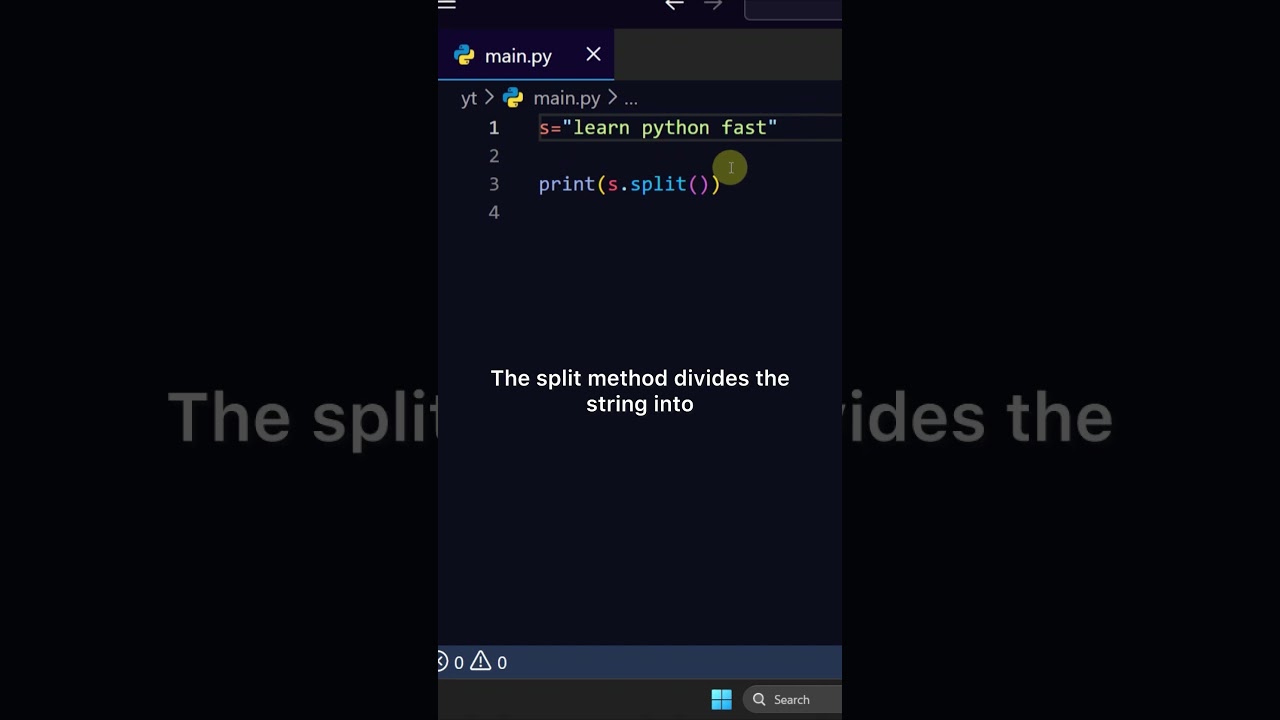
SELECT * vs naming your columns, timed from Python (psycopg 3) on Postgres 17.11: 1,000,000 users, 1,000 rows fetched per query.
With a 2 KB text column (a "bio", stored out of line in Postgres's TOAST table): SELECT * 4.57 ms and 2.1 MB of row data · SELECT id, name 0.29 ms and 17 KB. Naming the columns was 16× faster.
Same rows without the bio: SELECT * 0.87 ms · SELECT id, name 0.29 ms. Most of that gap is psycopg turning the timestamptz column into Python datetime objects (every column but the timestamp: 0.40 ms).
Selecting only columns in an index (created_at, id) gave an index-only scan with 0 heap fetches.
Why: Postgres reads whole rows from its pages either way; what changes is what it sends and what the client decodes. Large text and JSON values are moved to the TOAST table and read only when a query selects them.
Setup: one connection, all queries alternating, data in memory (warm cache), middle of 7 runs, each the average of 20 queries. The bio is random base64, so it doesn't compress; real text compresses and may stay in the row. TOAST table: 2.8 GB. Darwin arm64, Postgres 17.11, Python 3.14.7, psycopg 3.3.6, shared_buffers 128MB.
Narration: AI voice (ElevenLabs) - https://try.elevenlabs.io/aurora-algorithm











Share this link via
Or copy link